Language model · v0.3.0
Pico — Next Token Predictor
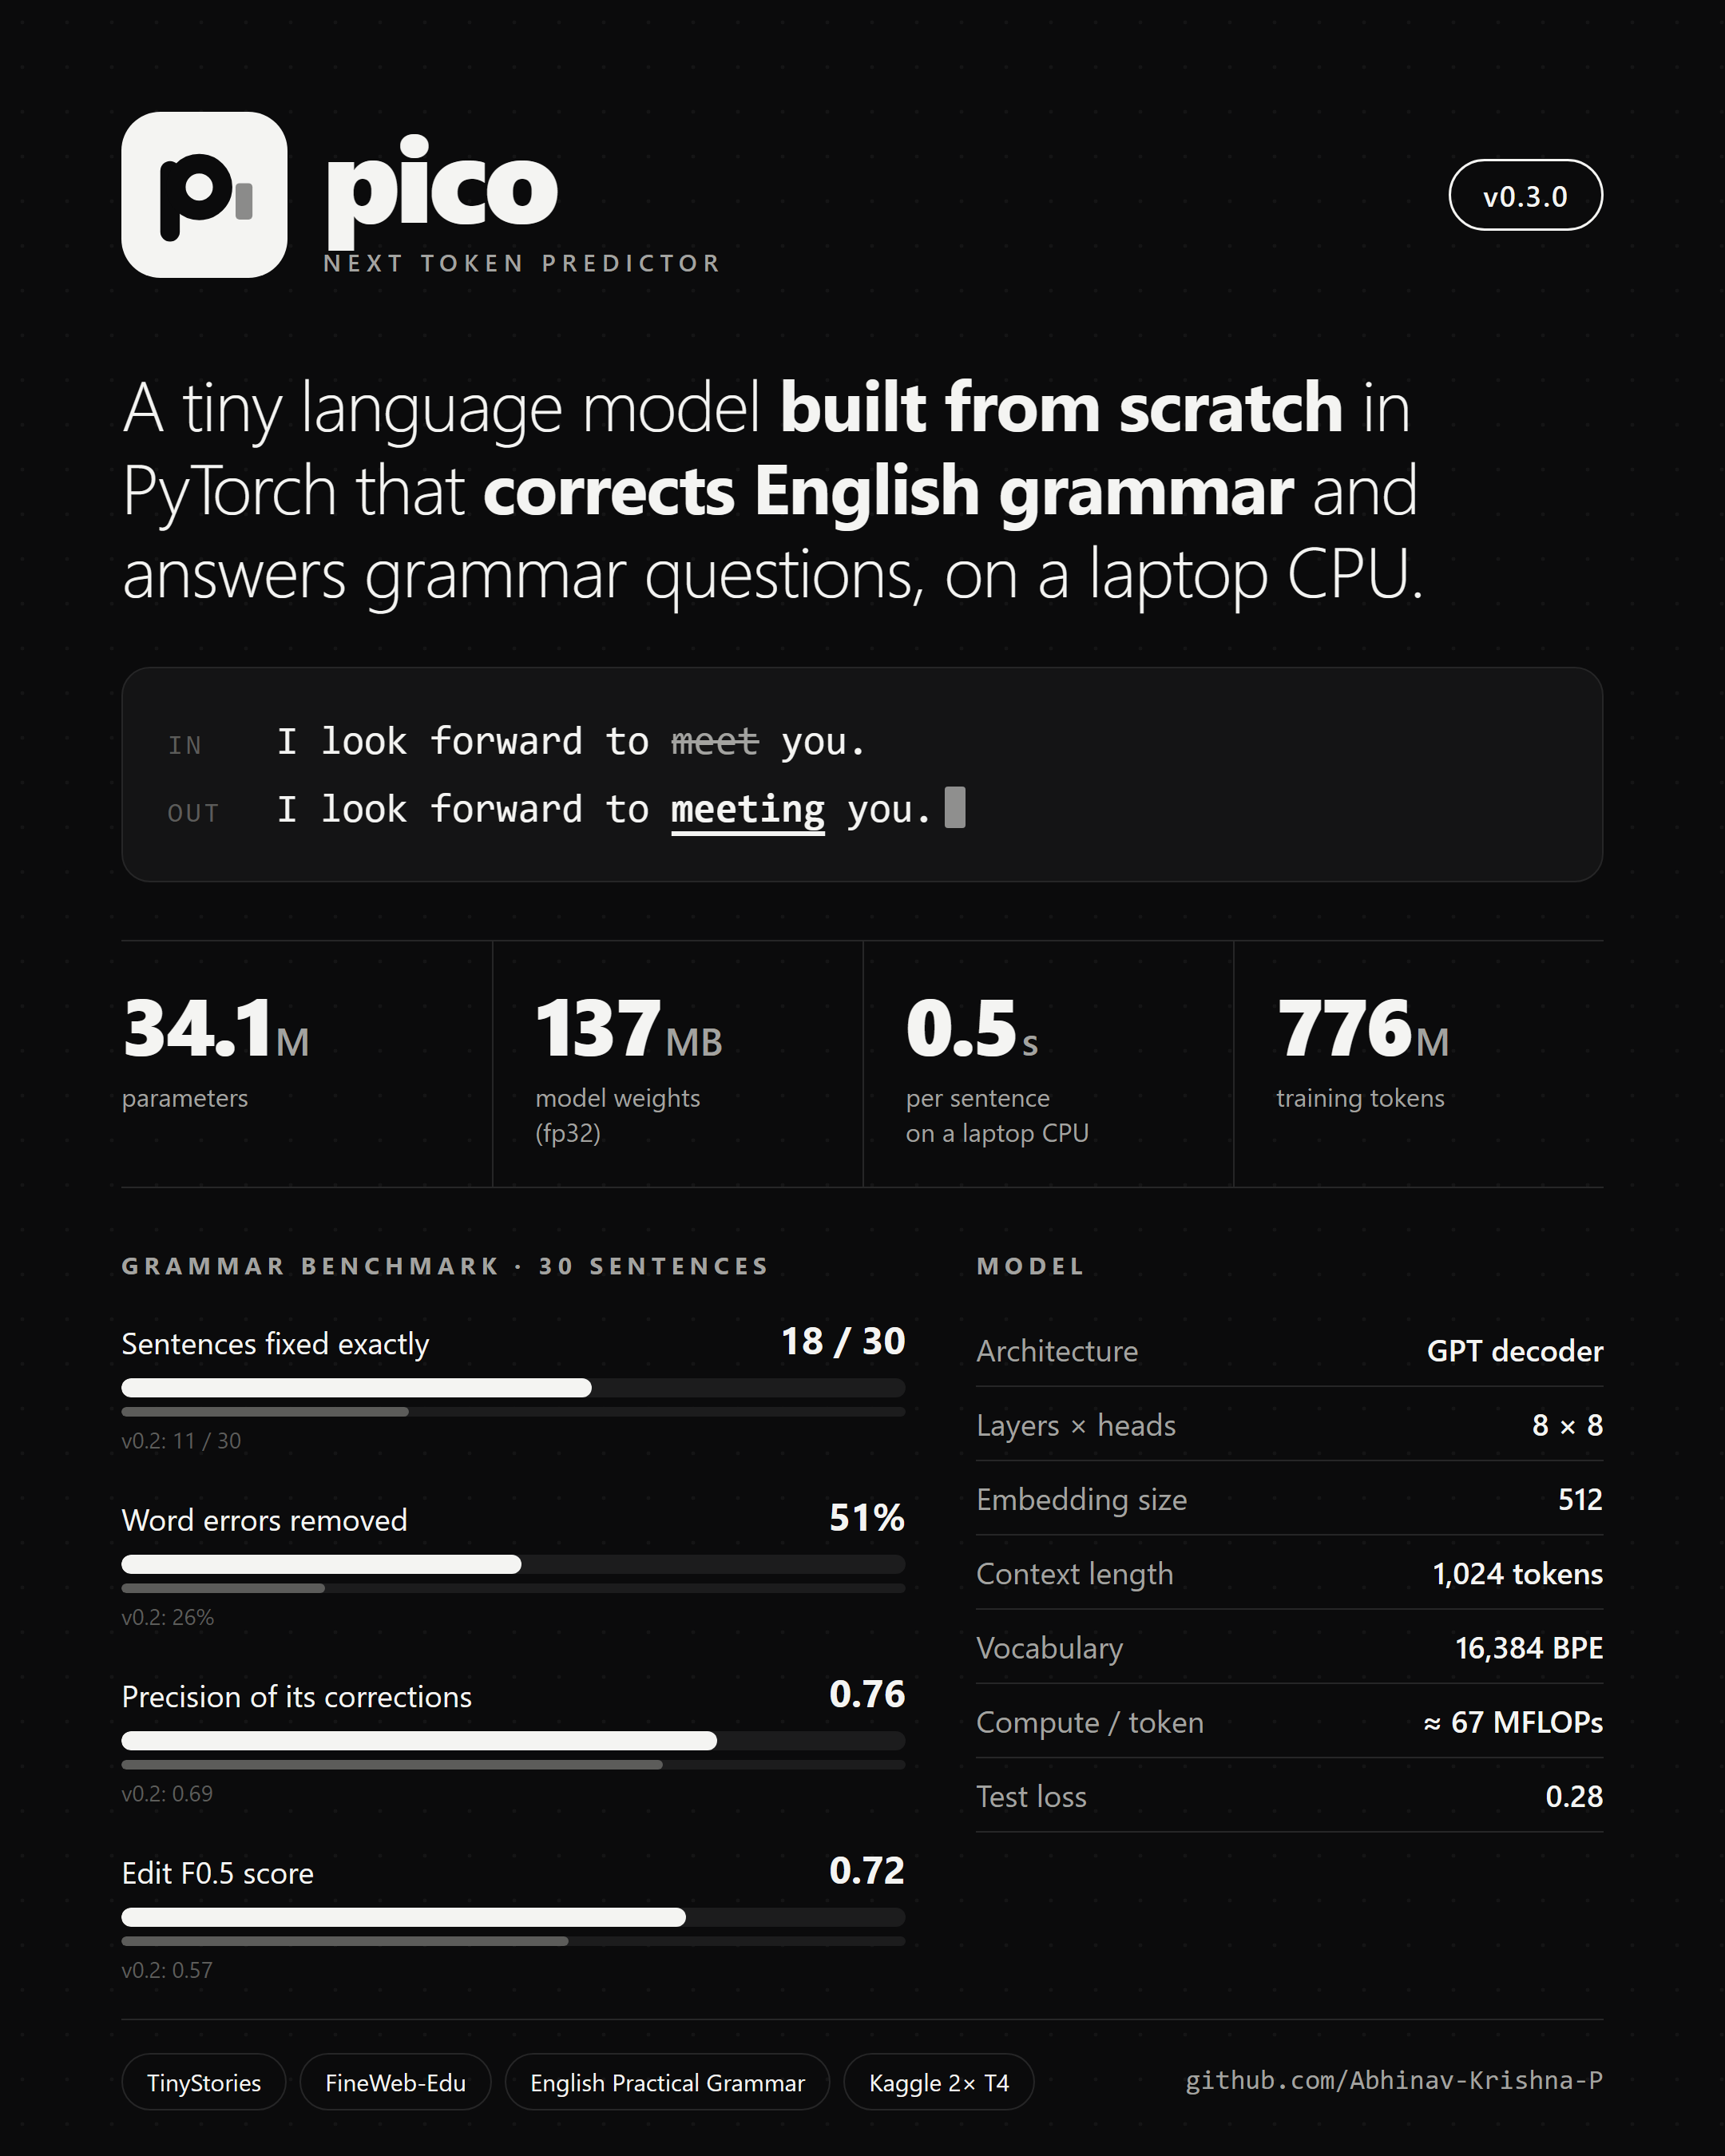
A 34.1M-parameter GPT-style language model built from scratch in PyTorch. Fine-tuned on grammar data, it corrects English sentences and answers grammar questions, running on a laptop CPU in about 0.27 s per sentence.
- GPT decoder (8 layers × 8 heads, 512-dim, 1,024-token context) with a KV cache and a 16,384-token SentencePiece BPE tokenizer
- Pre-trained on 776M tokens (TinyStories + FineWeb-Edu) on free Kaggle 2× T4 GPUs
- Fine-tuned in stages on 485k grammar pairs, my English Practical Grammar dataset, 2.19M cLang8 learner sentences and real learner essays
- Fixes 25/30 benchmark sentences exactly, edit precision 0.93, F0.5 0.90; ERRANT F0.5 0.41 on CoNLL-2014 and 0.54 on JFLEG
0M parameters
0M training tokens
0/ 30 sentences fixed